Kushal Kafle

Senior Research Scientist
Adobe Research

kushalkafle [at] gmail [dot] com

About Me

I am a Senior Research Scientist at Adobe Research, where I lead the development of Adobe's vision-language foundation models across the full lifecycle: data, training infrastructure, new algorithms, and product transfer. Our embedding models power features in Firefly, Lightroom, Premiere Pro, Adobe Express, and Adobe Stock (see Tech Transfers), and in the last few years we have also been building multimodal LLMs / vision-language models (VLMs).

My research interests include representation learning, benchmarks and evaluations that probe what these models actually understand, and building models that are robust, fair, and right for the right reasons.

I received my Ph.D. from the Chester F. Carlson Center for Imaging Science at Rochester Institute of Technology, advised by Christopher Kanan, where I worked on visual question answering and language-grounded visual understanding.

Kushal Kafle

News

Show older news
  • Dec 2021 Invited lecture on vision-language models and VQA at the 3rd Nepal Winter School in AI.
  • Oct 2021 Papers at CVPR 2021 and ICCV 2021. [1][2]
  • Jul 2021 Invited talk on bias in machine learning at the SIGIR eCom 2021 workshop.
  • Dec 2020 Papers at ACL 2020, ECCV 2020, and NeurIPS 2020. [1][2][3]
  • Mar 2020 Started working at Adobe Research as a research scientist.
  • Feb 2020 Successfully defended my Ph.D. dissertation. [1]
  • Mar 2019 Joining Microsoft Research, Redmond as a research intern this summer.
  • Jan 2019 Co-organizing the second Workshop on Shortcomings in Vision and Language (SiVL) at NAACL 2019.
  • Nov 2018 Successfully defended my thesis proposal (advancement to candidacy).
  • Jul 2018 Co-organizing the Workshop on Shortcomings in Vision and Language (SiVL) at ECCV 2018.
  • May 2017 Started a research internship at Adobe Research.

Tech Transfers

I lead Adobe's vision-language foundation model efforts: image-text embedding models and, in the last few years, multimodal LLMs / VLMs. The embedding models are already used throughout Adobe products; the VLM work is moving from exploration toward product. Some of the shipped features:

Adobe Express and Adobe Stock

Adobe Express and Adobe Stock

2023 – present

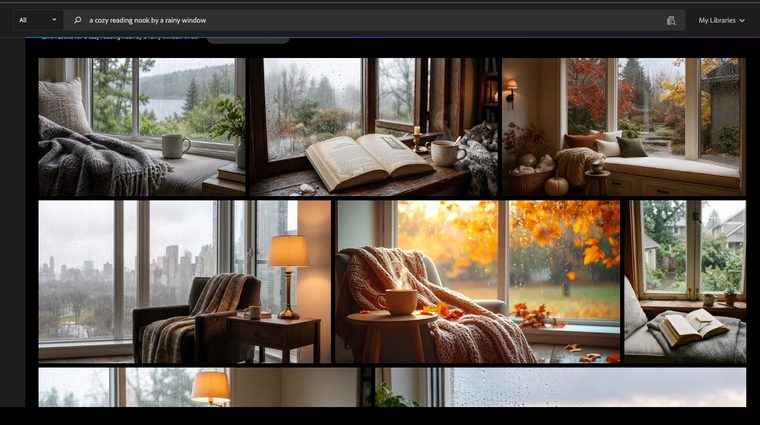
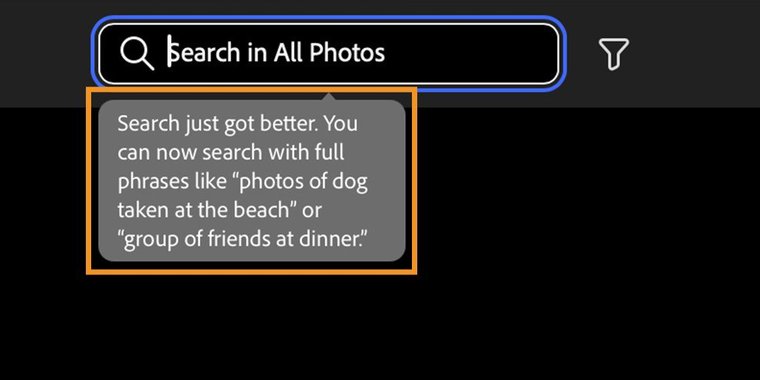
Natural-language and image search for templates in Adobe Express (+46% click-through) and for assets in Adobe Stock, plus "More like this" template similarity in Express. Search has since grown to multilingual, behavior-tuned, and steerable, and now runs on a new generation of our foundation model.
Adobe Firefly Image Generation

Adobe Firefly Image Generation

2023 – 2025

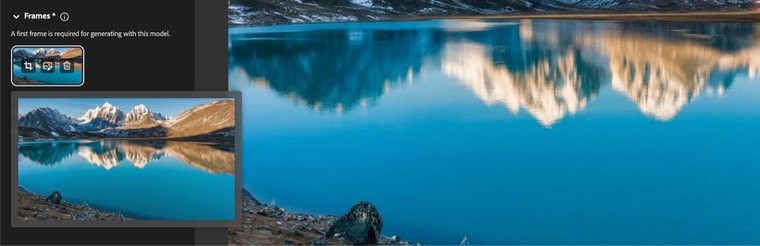
Firefly Image 1, 2, and 3 used our text and image encoders for their reference features, including Style Reference uploads, generating similar images, and using images as references. Our models also power Firefly's NSFW safety filter, used for both image and video generation, and the classifiers that filter its training data.

Firefly Image-to-Video

Firefly Image-to-Video

2025

Features from our image-text encoders were key to improving prompt coherence and bias handling for the image-to-video launch.

Premiere Pro Media Intelligence

Premiere Pro Media Intelligence

2025

Visual search in Premiere Pro's Media Intelligence and Search panel, built with the video team on our image-text foundation model.

Other Uses Across Adobe

Other Uses Across Adobe

2023 – present

The same models are used elsewhere across Adobe, including:

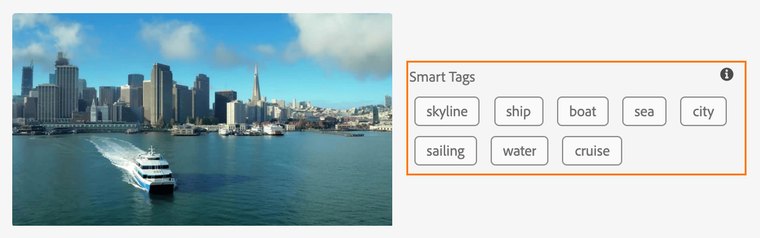
  • Smart Tags in Adobe Experience Manager.
  • Prompt-free object compositing in Photoshop (beta).
  • Visual encoders for our multimodal LLM research.

Research

List last updated November 4, 2026. For the latest, see Google Scholar.

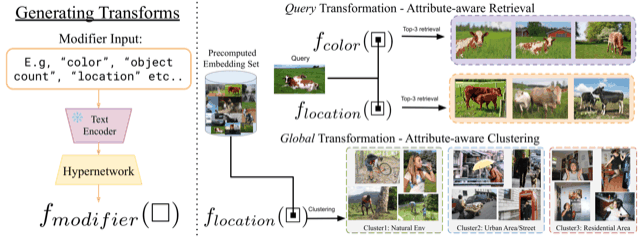
Controlling Embedding Spaces with Text-Conditioned Transformations

Joseph Fioresi, Fabian Caba Heilbron, Pankaj Nathani, Mubarak Shah, Kushal Kafle
ECCV 2026

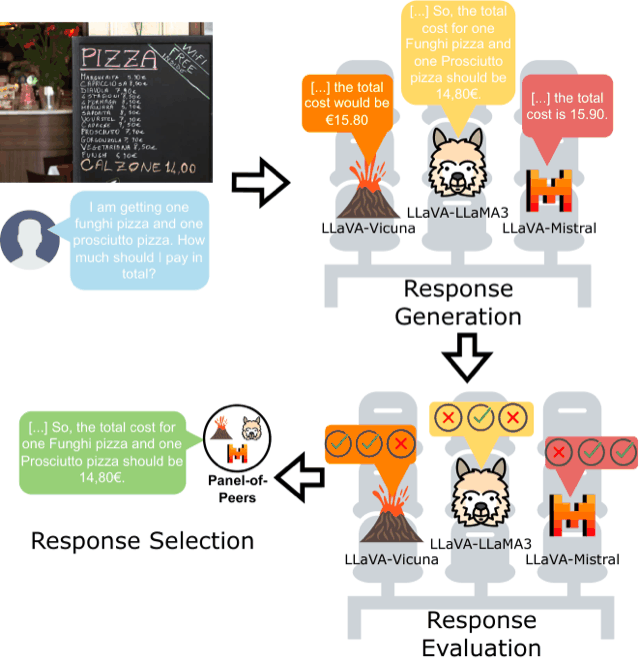
Improving Large Vision and Language Models by Learning from a Panel of Peers

Jefferson Hernandez, Jing Shi, Simon Jenni, Vicente Ordonez, Kushal Kafle
ICCV 2025

FairDeDup: Detecting and Mitigating Vision-Language Fairness Disparities in Semantic Dataset Deduplication

Eric Slyman, Stefan Lee, Scott Cohen, Kushal Kafle
CVPR 2024

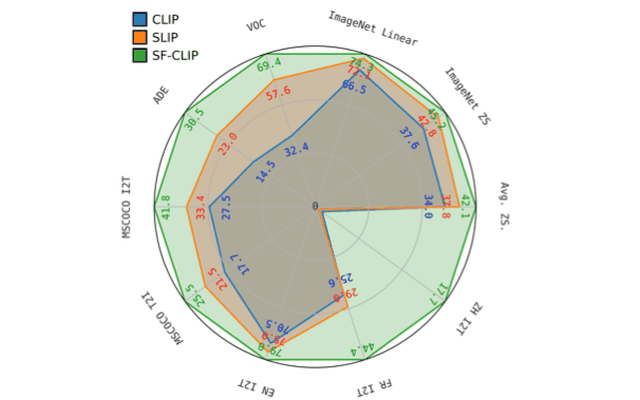
Building Vision-Language Models on Solid Foundations with Masked Distillation

Sepehr Sameni, Kushal Kafle, Hao Tan, Simon Jenni
CVPR 2024

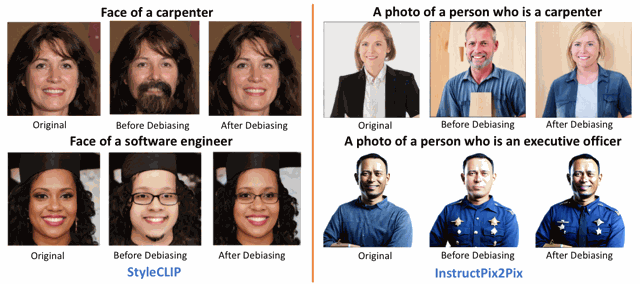
Discovering and Mitigating Biases in CLIP-Based Image Editing

Md Mehrab Tanjim, Krishna Kumar Singh, Kushal Kafle, Ritwik Sinha, Garrison W. Cottrell
WACV 2024 Oral Presentation (2.6% of submissions)

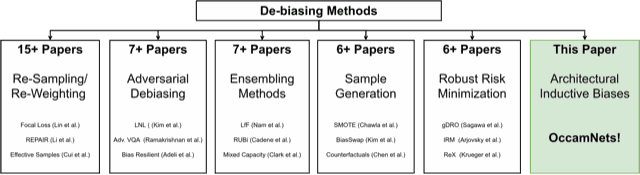
OccamNets: Mitigating Dataset Bias by Favoring Simpler Hypotheses

Robik Shrestha, Kushal Kafle, Christopher Kanan
ECCV 2022 Oral Presentation (2.7% of submissions)

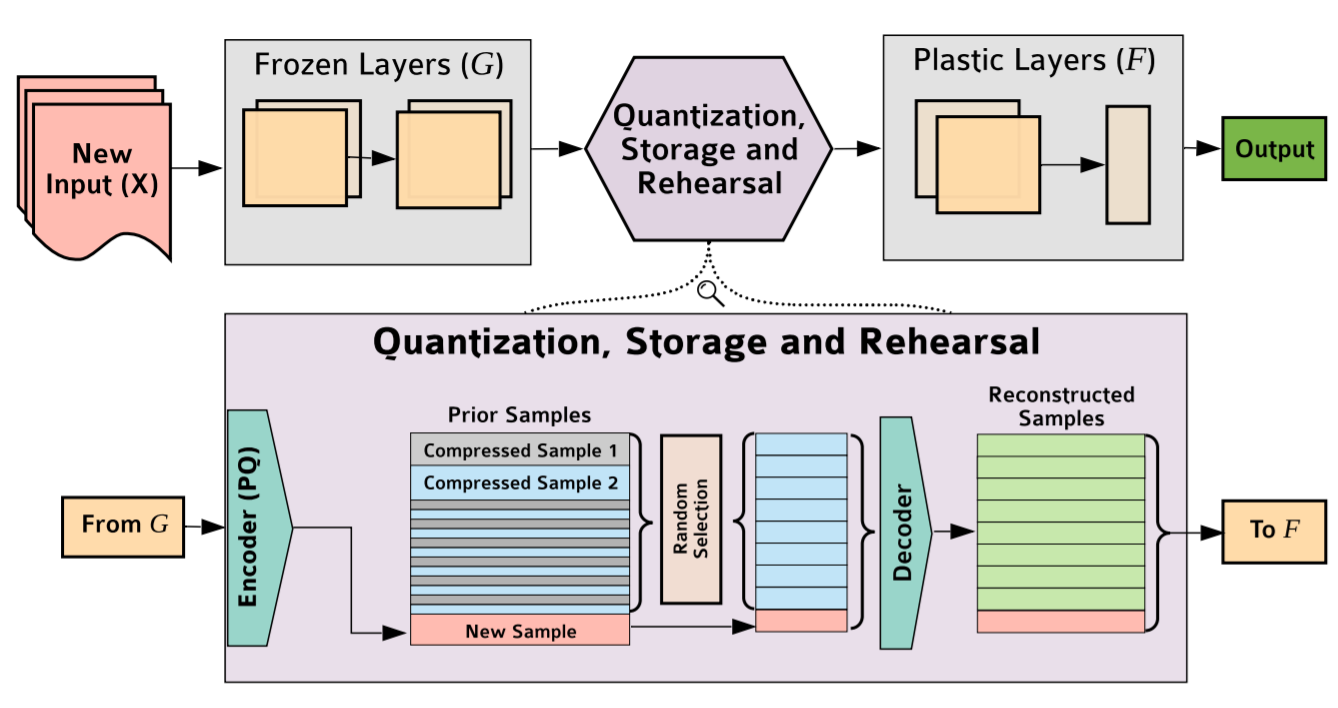
REMIND Your Neural Network to Prevent Catastrophic Forgetting

Tyler L. Hayes*, Kushal Kafle*, Robik Shrestha*, Manoj Acharya, Christopher Kanan
ECCV 2020 * equal contribution

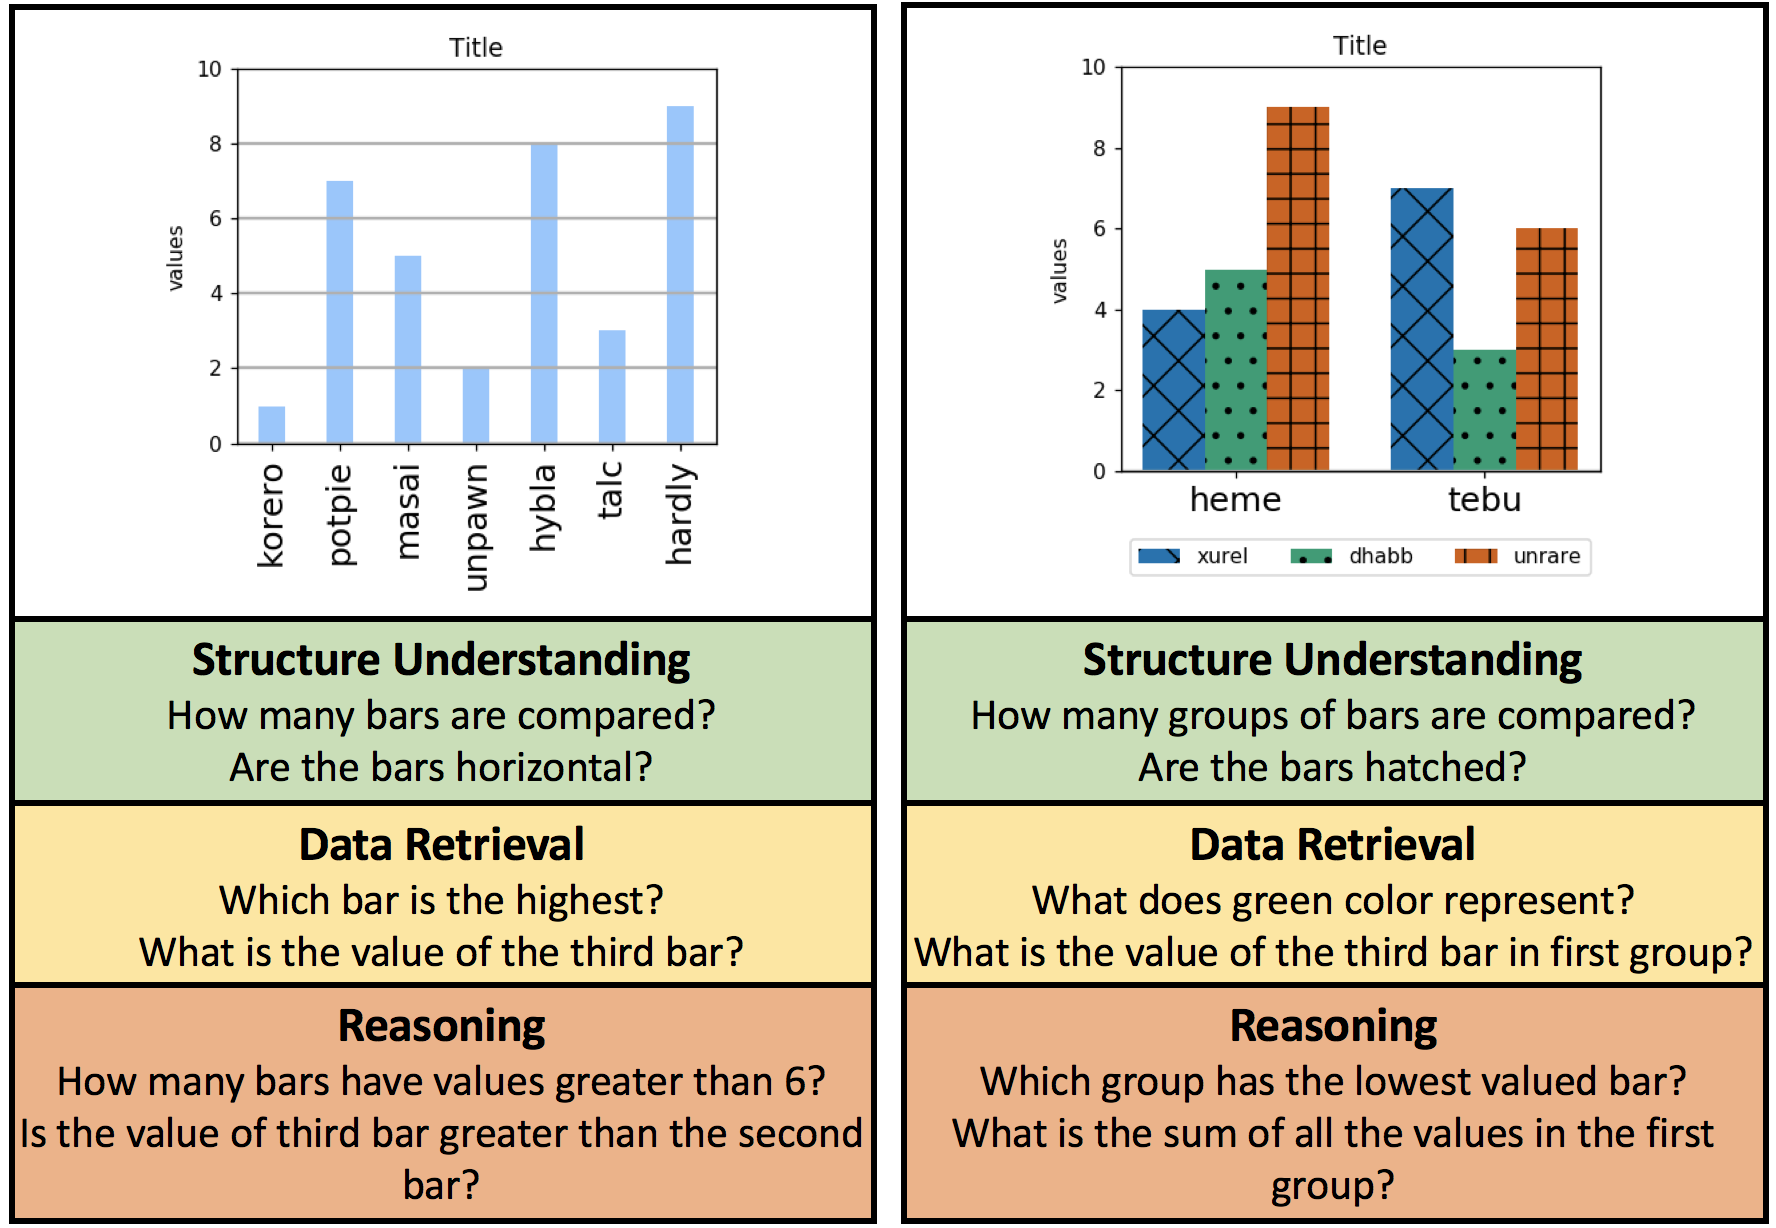
DVQA: Understanding Data Visualizations via Question Answering

Kushal Kafle, Brian Price, Scott Cohen, Christopher Kanan
CVPR 2018

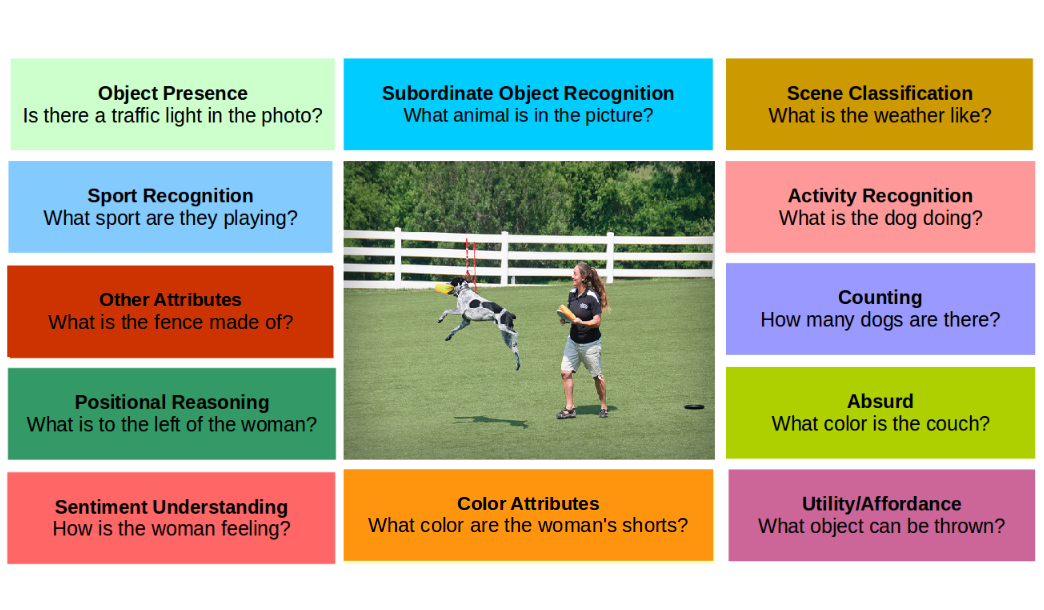
An Analysis of Visual Question Answering Algorithms

Kushal Kafle, Christopher Kanan
ICCV 2017

Talks

Misc

I have an Erdős number of four!

What follows is some long-winded collaboration lineage hunting, but you can't deny the facts! Kushal Kafle → Hao Tan → Leonidas Guibas → János Pach → Paul Erdős. Here's the link.

I have some impressive academic lineage!

Norbert Wiener is my grand-grand-grand-mentor (via Christopher Kanan, Garrison Cottrell, and Michael Arbib), and David Hilbert and Bertrand Russell are my grand-grand-grand-grand-mentors. It only gets better from there! Another branch runs through William Feller, Richard Courant, Jacob Rosanes, and Rudolf Lipschitz, and if you keep following it, you eventually encounter some really big-shot names: Dirichlet, Fourier, Poisson, Laplace, and Lagrange. Along the way there are also David Rumelhart, Warren McCulloch, and Rudolf Kalman. Talk about standing on the shoulders of giants! Here's the link.