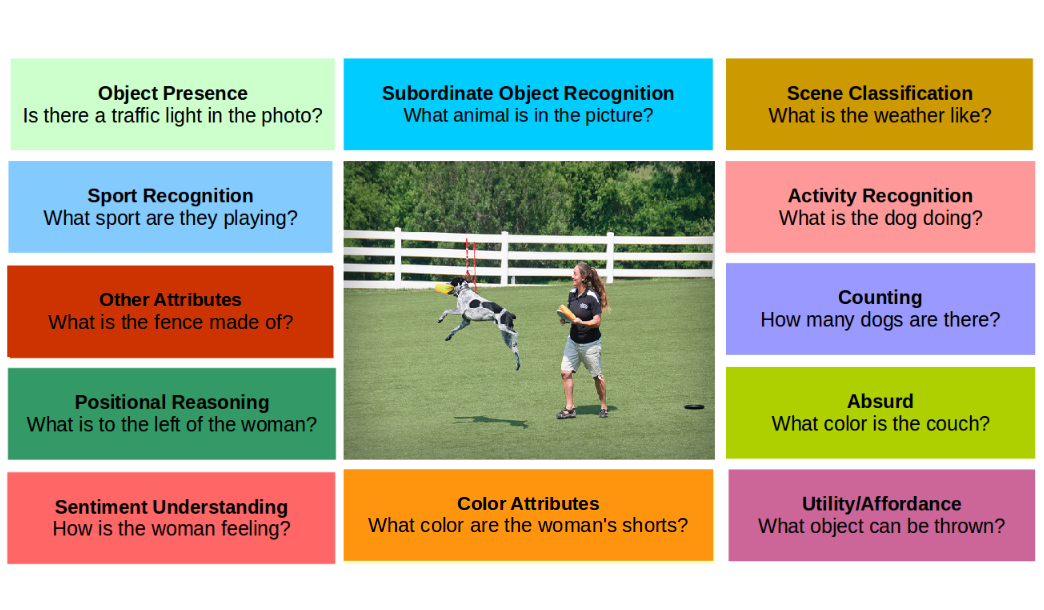
Visual question answering (VQA) is a challenging vision and language problem that demands a wide range of language and image understanding abilities. However, studying the abilities of current VQA systems is very difficult due to critical problems with bias and a lack of well-annotated question types. The Task Directed Image Understanding Challenge (TDIUC) divides VQA into 12 constituent tasks, making it easier to measure and compare the performance of VQA algorithms.
VQA is interesting because it encompasses many other computer vision problems, e.g., object detection, object classification, attribute classification, positional reasoning, and counting. Truly solving VQA requires an algorithm to solve all of them. Because prior datasets are heavily unbalanced toward certain kinds of questions, good performance on less frequent kinds of questions has negligible impact on overall performance. For example, object presence questions are far more common than questions requiring positional reasoning, so an algorithm that excels at positional reasoning cannot showcase its abilities. TDIUC's metrics compensate for this bias, so good performance on TDIUC requires good performance across kinds of questions. Many questions in other datasets can also be answered from the question alone, so TDIUC introduces absurd questions that require an algorithm to look at the image to decide whether the question even applies.
TDIUC at a glance
- 12 question types grouped by underlying task, including absurd questions
- 167,437 images from MS-COCO and Visual Genome
- 1,654,167 question-answer pairs from three distinct sources
- 4 new evaluation metrics designed to compensate for bias
- 6 new experimental setups to answer crucial questions about VQA algorithms